Gemini 3.8 Live Explained — Speech-to-Speech, Not a Recap Engine

TL;DR — As of 2026-09-16, Google launched Gemini 3.8 Live and 3.8 Live Extended Thinking in the Live API on 2026-09-15: native speech-to-speech, 97-language mid-call switch, async tool calls, and visual grounding ($0.005/min in, $0.018/min out). Extended Thinking leads Artificial Analysis Speech-to-Speech at 82.6. Pair Google's real-time voice intelligence with BibiGPT's long-context notes workflow to turn lectures, podcasts, and recordings into searchable chapter summaries.

Event · 2026-09-15 Speech-to-speech Live demo below

Explore AI-powered notes and video summaries

Paste a podcast, lecture, or meeting URL — BibiGPT turns it into timestamped chapters, a full transcript, and interactive Q&A. Pair cutting-edge models with structured knowledge extraction.

Add BibiGPT as a preferred source on Google See more BibiGPT in Top Stories and AI answers.

Key facts (90-second read)

As of 2026-09-16, Google put Gemini 3.8 Live and 3.8 Live Extended Thinking in the Live API on 2026-09-15: native speech-to-speech, 97-language hot-swap, async tool calls, visual context. Audio in $0.005/min, out $0.018/min. Extended Thinking leads Artificial Analysis Speech-to-Speech at 82.6. This is a live conversation product, not a summary engine.

Features

What Google shipped on 2026-09-15

Public numbers from Google's Live API announcement and developer docs — not a claim that BibiGPT runs this model.

Native speech-to-speech, not a cascade

Gemini 3.8 Live reasons over incoming and outgoing audio in one model. Callers can interrupt, switch language mid-turn, or keep talking while a tool runs. That is a live call, not a recap.

82.6 Speech-to-Speech; $0.005 / $0.018 per minute

Google reports Gemini 3.8 Live Extended Thinking at 82.6 on Artificial Analysis Speech-to-Speech, ahead of GPT-Live-1-Astra. Audio input is $0.005/min and output $0.018/min. Those scores and list prices are Google's, restated here.

97 languages, visual context, dedicated Transcribe SKU

Live models understand and generate speech in 97 languages and can switch mid-conversation. Inputs include text, images, audio, and video. Same day, Gemini 3.5 Transcribe — a separate speech-to-text SKU, 85+ languages — landed in the Gemini API.

Why a live voice layer still leaves a notes gap

A smoother interruption does not timestamp last week's decision. Knowledge work still needs a file you can search next Tuesday.

Live talk is not a searchable archive

Gemini 3.8 Live can keep speaking while a tool call finishes in the background. After the call, you still need chapters, a transcript, and a quote you can find again. That job is async.

Meetings already eat ~30% of the week

Laxis State of Meetings 2026: knowledge workers sit through 21.7 meetings a week, about 30% of the work week. A cheaper live minute does not shrink that pile. A timestamped recap does.

Podcasts are time-locked, not supply-locked

Edison Infinite Dial 2026: US podcast listeners average 8 hours 24 minutes a week across 6.8 shows. The leftover episodes need a triage desk, not another live voice. A summary decides which hour is worth playing.

5 key changes (90-second read)

Headline shifts from Google's 2026-09-15 Gemini Live API launch.

  1. 1

    Native speech-to-speech instead of a cascade

    One model reasons over incoming and outgoing audio together. Interruptions, language switches, and backchannels stay in the same session. Older stacks that transcribe, then think, then speak wait for a turn to finish.

  2. 2

    Extended Thinking 82.6 on Speech-to-Speech

    Google reports Gemini 3.8 Live Extended Thinking at 82.6 on Artificial Analysis Speech-to-Speech, #1 overall, ahead of GPT-Live-1-Astra. Live itself placed second on Speech Agent Arena. Those scores are Google's evals, restated here, not a test we ran.

  3. 3

    $0.005/min in, $0.018/min out

    Audio input is $0.005 per minute and audio output $0.018 per minute on the Live API. GPT-Live-1's front-end layer is $0.05/min. List prices are Google's and OpenAI's, not a BibiGPT SKU.

  4. 4

    Async tools, visual context, 97 languages

    Tool calls run in the background while audio keeps streaming. Inputs: text, images, audio, video. The models understand and generate speech in 97 languages and can switch mid-conversation. Developer docs list gemini-3.8-live as the low-latency default.

  5. 5

    A live layer, plus a separate Transcribe SKU

    Same day, Gemini 3.5 Transcribe landed in the Gemini API: dedicated speech-to-text, 85+ languages, streaming WER 4.0% / non-streaming 2.6% (Artificial Analysis, cited by Google). After the session you still need chapters you can search next week. That is the BibiGPT path, not a Live integration.

3 typical scenarios for BibiGPT users

Where a live voice layer helps — and where a notes workflow still does the work.

You host or cut a weekly podcast

US listeners average 8 hours 24 minutes a week across 6.8 shows (Edison Infinite Dial 2026). A live voice API does not triage the backlog. Generate chapters first, then decide which hour is worth a full listen.

You sit through 20+ meetings a week

Laxis 2026: 21.7 meetings a week, about 30% of the work week. A cheaper live minute is useful on the call. Next Tuesday you still need the sentence that was decided. File the recording; search the transcript.

You already have a lecture recording

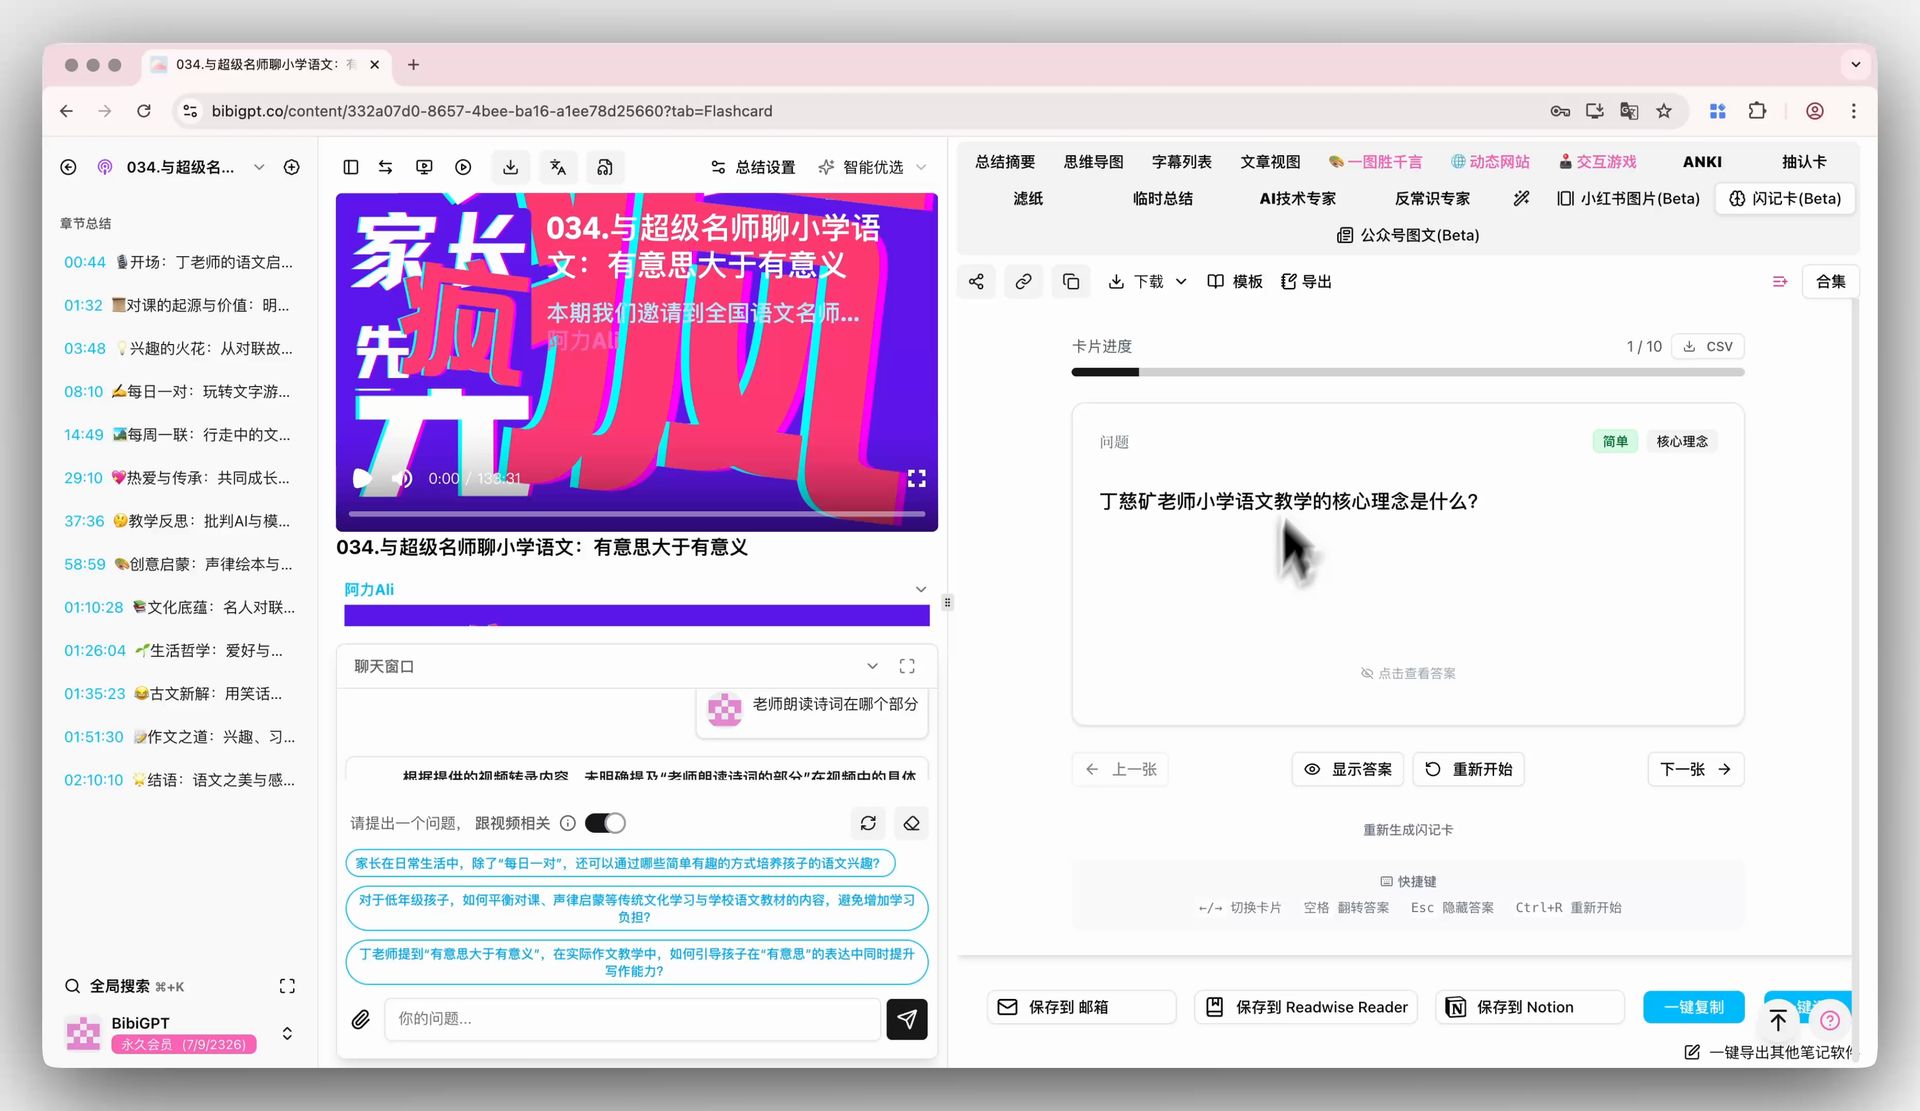
Paste the URL. Get chapters before you press play, jump to a timestamp, export Markdown. Gemini 3.8 Live does not have to be in the loop. The notes workflow already runs on files you own.

Related BibiGPT pages

The notes workflow is the product. The blog owns the long comparison. This page owns the event.

Sources

Launch claims come from Google's announcement and independent coverage. Last updated 2026-09-16. Not an integration claim.

Gemini 3.8 Live Capabilities & Notes Workflow FAQ

What is Gemini 3.8 Live?

Gemini 3.8 Live is Google's native speech-to-speech model in the Live API, released on 2026-09-15. One multimodal model reasons over incoming and outgoing audio simultaneously, handling natural interruptions and mid-turn language switches without chaining separate transcription and synthesis steps.
What are Gemini 3.8 Live benchmarks and API pricing?

Gemini 3.8 Live Extended Thinking leads Artificial Analysis Speech-to-Speech benchmarks at 82.6, ahead of GPT-Live-1-Astra. Live API audio pricing is $0.005 per minute for audio input and $0.018 per minute for audio output, supporting async tool execution and visual grounding across 97 languages.

How does Gemini 3.8 Live differ from speech-to-text summary engines?

Gemini 3.8 Live powers low-latency, real-time voice conversations, but does not archive meetings or generate searchable knowledge notes. In contrast, BibiGPT pairs with models like Gemini 3.8 Flash to transform hours of recorded video and audio into timestamped chapters, mind maps, and interactive QA.

Loved by creators, students & researchers

Why people use BibiGPT to turn videos into text every day.

Trusted by 50,000+ users worldwide

★★★★★

“I paste a link and get clean captions in seconds — it saves me hours of retyping every single week.”

Maya R.

Content Creator · Repurposes short videos

★★★★★

“Exporting the transcript lets me review new words at my own pace instead of pausing the video constantly.”

Daniel K.

Language Learner · Studies with real videos

★★★★★

“Accurate, timestamped text I can quote directly. It has quietly become part of my daily workflow.”

Priya S.

Researcher · Cites public talks

Frequently Asked Questions

Ask us anything!

Popular guides

Keep the live call. File the recap.

Paste a podcast, lecture, or meeting recording into BibiGPT. You get chapters, a searchable transcript, and follow-up Q&A. Gemini 3.8 Live handles the interruption. The notes still need a timestamp.